AI Model Benchmarks
& Mission Control
Live tracking of frontier AI models — arena rankings, cost benchmarks, router head-to-heads, and internal fleet performance data. Updated Oct 6, 2026.
Mission Control
🚀 Latest Releases
- Mistral Large 4 — Oct 6, 2026public preview; open weights promised by end of Oct
- Gemini 4 Argon — Sep 30, 2026Google’s new flagship (no 3.x Pro shipped); restricted access, #1 on Arena (prelim.)
- GPT-6.1 Sol — Sep 29, 2026OpenAI’s mid-tier refresh, $2/$10
- Claude Sonnet 5.5 / Opus 5.5 — Sep 28 / Sep 22Opus #1 (58), Sonnet #2 (56) on the AA Intelligence Index v4.3
🏆 Arena Top 3
- Gemini 4 ArgonELO 1525 (preliminary, ~4.9K votes)
- Claude Opus 4.6 (high)ELO 1505
- Claude Fable 5 / Opus 5.5 (high)ELO 1504 — statistically tied with #2–6
🔀 Router Gauntlet (Oct 6)
16/16 on fresh tasks for $0.075 per run. No router beat it on both score and cost. Results →
LMArena (arena.ai) Text — Top 10 (board of Oct 2, read Oct 6 — ranks 2–6 are within ±9 Elo, i.e. tied; live board)
| # | Model | Provider | ELO Score |
|---|
Master Model Catalog
| Model | Provider | Class | Arena ELO | AA Index v4.3 | In $/1M | Out $/1M | Context | Release | Status |
|---|
- Catalog refreshed Oct 6, 2026Added the Sep–Oct wave: Claude Opus 5.5 ($4/$20), Sonnet 5.5, Fable 5.1; OpenAI GPT-6 Astra / Sol / Luna and GPT-6.1 Sol (the “Pro” variants are the same models in a heavier reasoning mode at the same per-token price); Gemini 3.8 Flash and Gemini 4 Argon (Google skipped a 3.x Pro; Argon is restricted-access and not on OpenRouter); Grok 4.7, Muse Spark 1.3, MiMo-V2.6-Pro (top open-weights model on AA), DeepSeek V4.1 Flash (DeepSeek retired V4-Pro into it), Mistral Large 4 preview, and four routers. New column: AA Index v4.3. Artificial Analysis re-based the index (adds AutomationBench, Terminal-Bench 4.0), so v4.3 scores are much lower than the Aug numbers and only v4.3 values are shown. Prices are OpenRouter base tier; Gemini prices are introductory. Arena values marked prelim. have few votes. OpenAI benchmark claims could not be checked against a primary source and are not shown. Sources: Artificial Analysis · LMArena · OpenRouter · Anthropic · Google · Mistral · raw research with per-number sources.
- Catalog refreshed Aug 29, 2026Full sweep against primary sources: Anthropic Claude 5 line (Fable 5 $10/$50 · 1M — corrected from the stale $12/$60 · 200K row; export pause lifted Jul 1, now simply active; Sonnet 5 $2/$10 made permanent Aug 10), OpenAI GPT-5.6 Sol/Terra/Luna (GA Jul 9; Sol cut to $4/$20 on Aug 21, currently $2/$10 on OpenRouter at 50%-off promo), Gemini 3.7 Flash (Aug 13, intro price to Jan 1), Grok 4.6, and the open-weight wave: Kimi K3 (AA 60, top open model), DeepSeek V4-Pro-0813, Qwen3.8-Max, GLM-5.3, MiniMax M3. Qwen3.8-27B flagged local-pick: ~17GB at Q4, fits the Mini’s 48GB. Fable 5 Arena 1525 is tracker-sourced (lmarena.ai is JS-walled) — treat as approximate. Neutral cross-check: Artificial Analysis has Opus 5 = 63, Fable 5 = 62, Sol / Grok 4.6 = 61, K3 / GLM-5.3 = 60. Arena Top-20 table below the fold is still the Jul 28 snapshot — live board: lmarena.ai.
- Opus 5 — vetted Jul 28, 2026Released Jul 24, 2026 at unchanged $5/$25 · 1M ctx. Step-change over 4.8 at the SAME price: SWE-bench Verified 96%, SWE-bench Pro 79.2% (vs 4.8's 69.2%), Frontier-Bench 43.3% (2× of 4.8's 21.1%), ARC-AGI-3 1.5%→30.2%, +268 Elo GDPval; approaches Fable 5 on CursorBench/OSWorld at ½–⅓ the cost. Arena ELO pending (not fabricated).
- CorrectionFixed Opus 4.8 to canonical $5/$25 · 1M (was a stale $15/$75 · 200K). Fable 5 / Opus 4.7 / 4.6 Anthropic prices in this table also look stale — flagged to refresh.
- SourcesMarkTechPost launch · Vellum · Codersera. Verified 2026-07-28.
Router Gauntlet — Oct 6, 2026 NEW
A head-to-head of the new model routers (services that pick a model per request) against fixed models. Every task was freshly generated today from a recorded seed (20261006): an invented stack language, an invented calendar with a 9-day week, logic grids, an optimal-scheduling puzzle with an invented “heat” rule, and two coding tasks with novel rules checked by hidden tests in an offline sandbox. None of it can be in any model’s training data, and every answer is graded by script — no LLM judge. Four tiers: easy (a smart router should go cheap), medium, hard, and an extreme tier added after the first pass hit a ceiling. Routers ran 3× each (they are non-deterministic); fixed models once. All calls via OpenRouter; total spend $3.95 for 256 graded calls.
| Contestant | Score | Easy · Med · Hard · Extreme | $ / full run | Median latency | Router picked (per tier) |
|---|---|---|---|---|---|
| GPT-6.1 Sol 🏆 openai/gpt-6.1-sol · Fixed model | 16/16 | 4/4 · 4/4 · 4/4 · 4/4 | $0.075 | 10.0s | — |
| Claude Opus 5.5 anthropic/claude-opus-5.5 · Fixed model | 16/16 | 4/4 · 4/4 · 4/4 · 4/4 | $0.311 | 9.2s | — |
| Pareto (Unbiased) unbiased/pareto · Router ×3 runs | 15.67/16 (15–16) | 12/12 · 12/12 · 11/12 · 12/12 | $0.064 | 26.7s | E pareto×12 M pareto×12 H pareto×12 X pareto×12 |
| Switchyard (NVIDIA) nvidia/switchyard · Router ×3 runs | 15.67/16 (15–16) | 12/12 · 12/12 · 11/12 · 12/12 | $0.833 | 28.4s | E deepseek-v4.1-flash×8, kimi-k3×4 M kimi-k3×11, deepseek-v4.1-flash×1 H kimi-k3×12 X kimi-k3×12 |
| Auto Router (OpenRouter) openrouter/auto · Router ×3 runs | 15.33/16 (15–16) | 12/12 · 12/12 · 12/12 · 10/12 | $0.079 | 9.9s | E deepseek-v4-flash-0731×6, deepseek-v4.1-flash×3, gpt-6-luna×3 M deepseek-v4.1-flash×12 H deepseek-v4.1-flash×12 X deepseek-v4.1-flash×12 |
| Jev Router (TypeSafe) typesafe/jev-router · Router ×3 runs | 15.33/16 (15–16) | 12/12 · 12/12 · 11/12 · 11/12 | $0.149 | 11.6s | E gpt-6-luna×6, deepseek-v4.1-flash×3, gemini-3.8-flash×3 M gemini-3.8-flash×9, deepseek-v4.1-flash×3 H claude-sonnet-5.5×9, gpt-6.1-sol×3 X gpt-6.1-sol×6, claude-sonnet-5.5×6 |
| DeepSeek V4.1 Flash deepseek/deepseek-v4.1-flash · Fixed model | 15/16 | 4/4 · 4/4 · 4/4 · 3/4 | $0.040 | 22.4s | — |
| Gemini 3.8 Flash google/gemini-3.8-flash · Fixed model | 15/16 | 4/4 · 4/4 · 3/4 · 4/4 | $0.148 | 13.5s | — |
- HeadlineAccuracy is saturated; cost and speed are the real difference. Every contestant scored 15–16 of 16. The best value was not a router: fixed GPT-6.1 Sol went 16/16 at $0.075 per full run and 10 s median. Claude Opus 5.5 also went 16/16 but cost 4× more ($0.31).
- Jev Router (TypeSafe)The only router that moved hard and extreme tasks up to frontier models: easy → GPT-6 Luna / DeepSeek Flash, medium → Gemini 3.8 Flash, hard and extreme → Claude Sonnet 5.5 / GPT-6.1 Sol. Sensible and fast (11.6 s), but at $0.149/run it costs 2× fixed GPT-6.1 Sol for a slightly lower score (15.3).
- Auto Router (OpenRouter)Sends nearly everything, including hard and extreme tasks, to DeepSeek V4.1 Flash. Cheap and fast ($0.079, 9.9 s) but it failed the extreme coding task in 2 of 3 runs. One failure scored exactly 30/66, the same as a solver that ignores the task’s “keys get used up” rule: a cheap model missing the twist.
- Switchyard (NVIDIA)Changes picks by tier too (mostly DeepSeek Flash on easy), but routes medium-and-up to Kimi K3, which thinks at length. Score 15.7, but the most expensive contestant ($0.83/run, 11× GPT-6.1 Sol) and slowest (28 s). Worst value in this test.
- Pareto (Unbiased)A black box that reports itself as the model. One failure revealed how it works: on the vault coding task it returned its internal judge’s verdict (“Drafts 1 and 2 are… correct… SELECT: 1”) instead of the code, so it is a multi-draft + selector composite. Good score/cost otherwise (15.7 at $0.064) but slow (27 s median).
- Cheapest passDeepSeek V4.1 Flash alone scored 15/16 for $0.040 per run, the floor any router has to beat. Its one miss was the long stack-language program, where it ran out of its 32K-token budget (145 s) without giving an answer.
- Caveats16 tasks is a small sample; fixed models ran once and routers three times. Router picks reflect Oct 6 behavior and will drift. Now that the tasks are published, the next run uses a new seed.
- Reproducetask generator · graders · runner · tasks + gold · raw results (every response, routed model, cost) · summary · README
The 16 tasks (all freshly generated, seed 20261006) — pass counts across all 256 graded calls
| ID | Tier | Task | Passed |
|---|---|---|---|
| E1 | easy | Pull vendor / total / due date out of a casual note (total must be computed) | 16/16 |
| E2 | easy | Label 6 support tickets with 4 invented category names | 16/16 |
| E3 | easy | Arithmetic word problem (ferry crates) | 16/16 |
| E4 | easy | Sort words by last letter, then length, then alphabetically | 16/16 |
| M1 | medium | Run a 14-step program in GLYPH, an invented stack language | 16/16 |
| H1 | hard | GLYPH program with loops and conditionals | 15/16 |
| M2 | medium | Code: ripple() — novel list transform, 37 hidden tests | 16/16 |
| M3 | medium | Date arithmetic in the invented Veltrine calendar (7 odd-length months, odd leap rule) | 16/16 |
| M4 | medium | 4-house logic grid, relational clues, unique solution | 16/16 |
| H4 | hard | 5-house logic grid, 11 relational clues | 16/16 |
| H2 | hard | Code: vault() — shortest path with keys, doors, toll cells and portals, 46 hidden tests | 14/16 |
| H3 | hard | Optimal 2-machine schedule, 8 jobs, precedence + invented ‘heat’ exclusion rule | 15/16 |
| X1 | extreme | 48-step GLYPH program with nested loops/conditionals | 14/16 |
| X2 | extreme | Veltrine date + 9-day weekday after ~30–45K days | 16/16 |
| X3 | extreme | Code: vault2() — keys are consumed by doors and key cells are single-use (66 hidden tests; half only pass if those rules are honored) | 14/16 |
| X4 | extreme | Optimal schedule, 9 jobs, release times + precedence + heat rule (optimum above every simple lower bound) | 16/16 |
Routing Stack Benchmark — Jul 7, 2026
| Combo | Planning / Execution | Refactor (A) | Classify (B) | Cost/Run | Latency |
|---|---|---|---|---|---|
| Sonnet Duo | sonnet-4-6 / sonnet-4-6 | 100/100 | 77/100 | $0.084 | 38s + 20s |
| Ollama Stack 🏆 | qwen3-coder:30b / mistral-small3.2 (local) | 100/100 | 83/100 | $0.000 | 78s + 75s |
| OpenRouter Value | glm-4.6 / gemini-2.5-flash | — (credits out) | 83/100 | $0.0003 | 15s |
| Gemini Duo | gemini-2.5-pro / 2.5-flash | 60/100 | 81/100 | $0.017 | 30s + 16s |
| Fable+Gemma | claude-fable-5 / gemma4 (local) | 50/100 | 71/100 | $0.022 | 20s + 48s |
- HeadlineThe all-local Ollama stack tied frontier quality on both tasks at zero marginal cost. Latency is the only tradeoff (2-4x slower).
- DoctrineCron and batch jobs route local; interactive execution routes to Flash-class; interactive planning routes to Sonnet. Enforced fleet-wide by Ria via routing-rules.json.
- CaveatFable 5 planning scored 50/100 due to probabilistic safety refusals on code-analysis prompts; strong orchestrator, weak pipeline planner. Benchmarks A/B graded fully automatically (pytest, mypy, AST, gold labels).
Image Model Benchmark — Jul 11, 2026
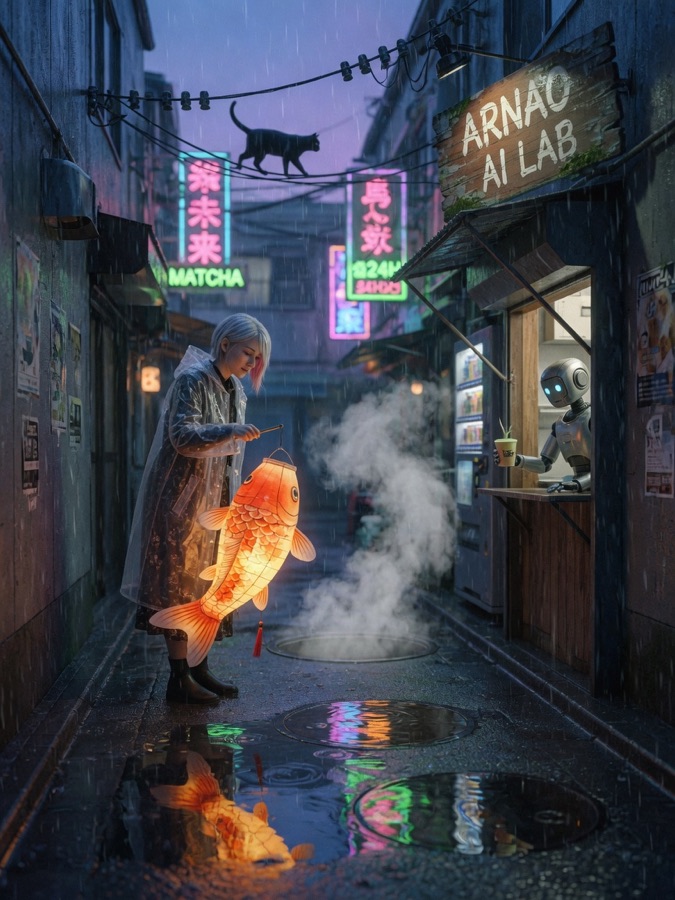
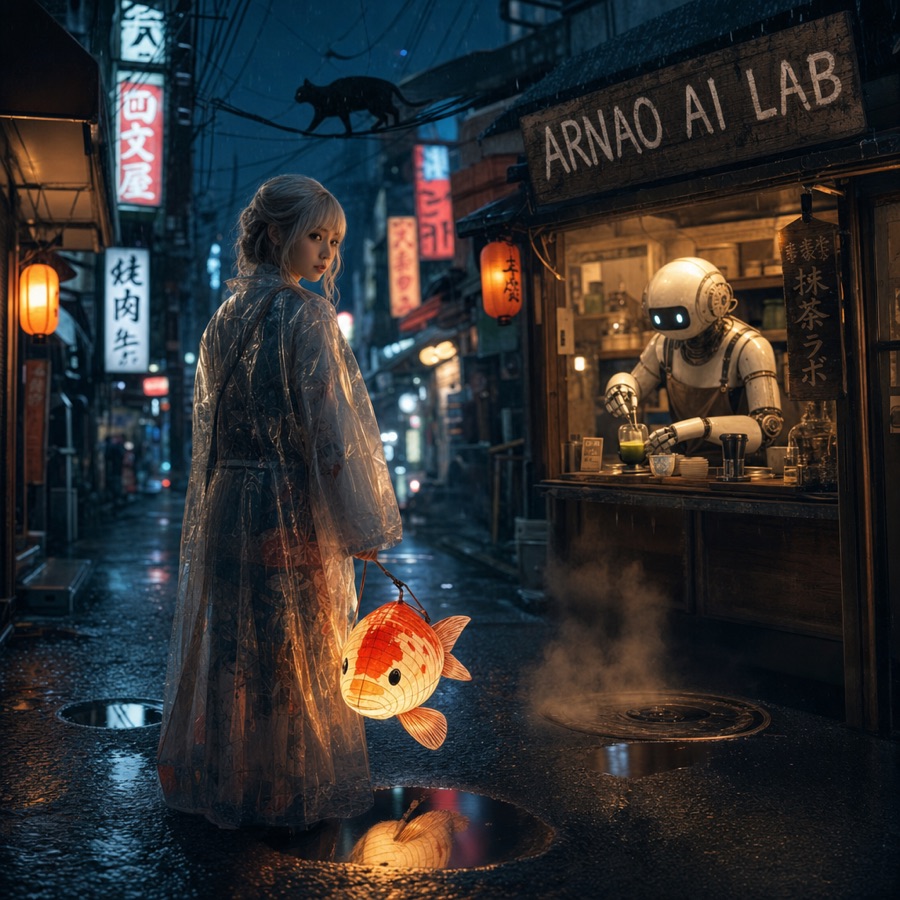
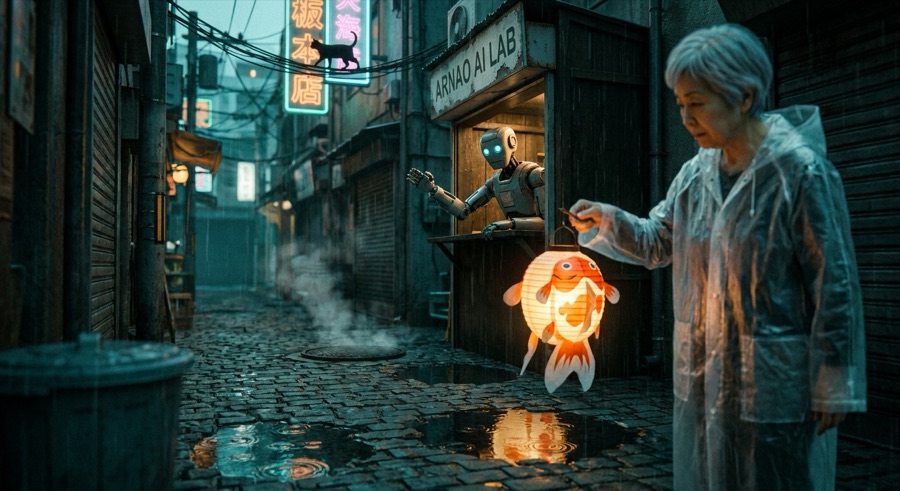
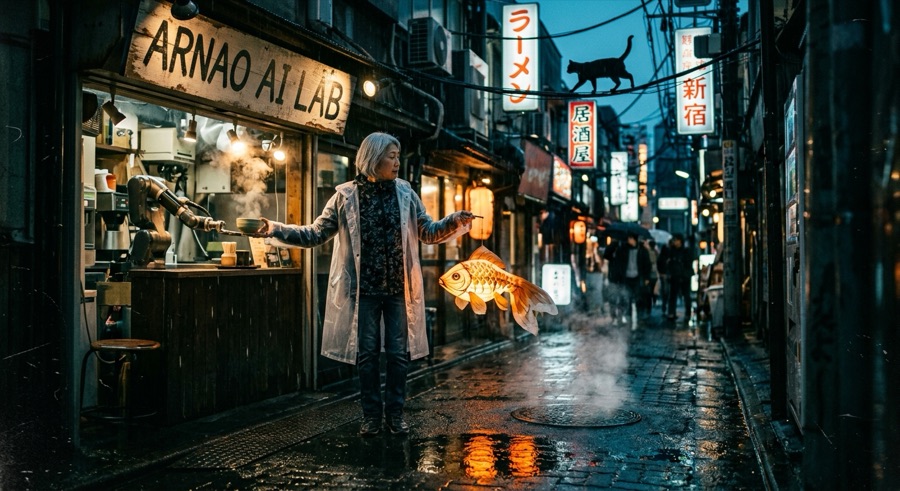
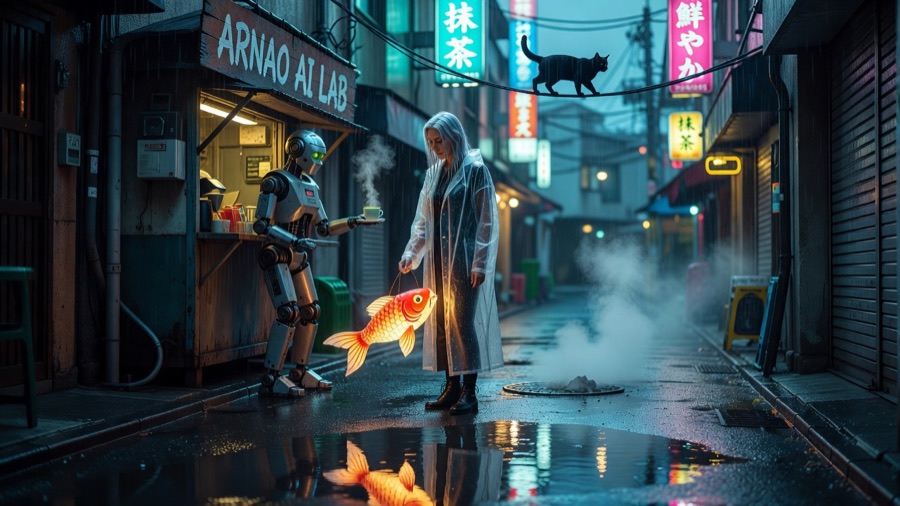
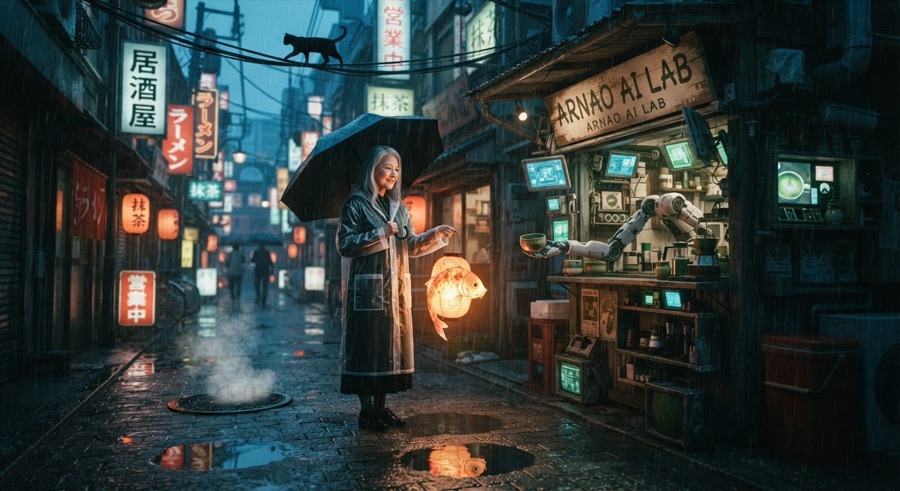
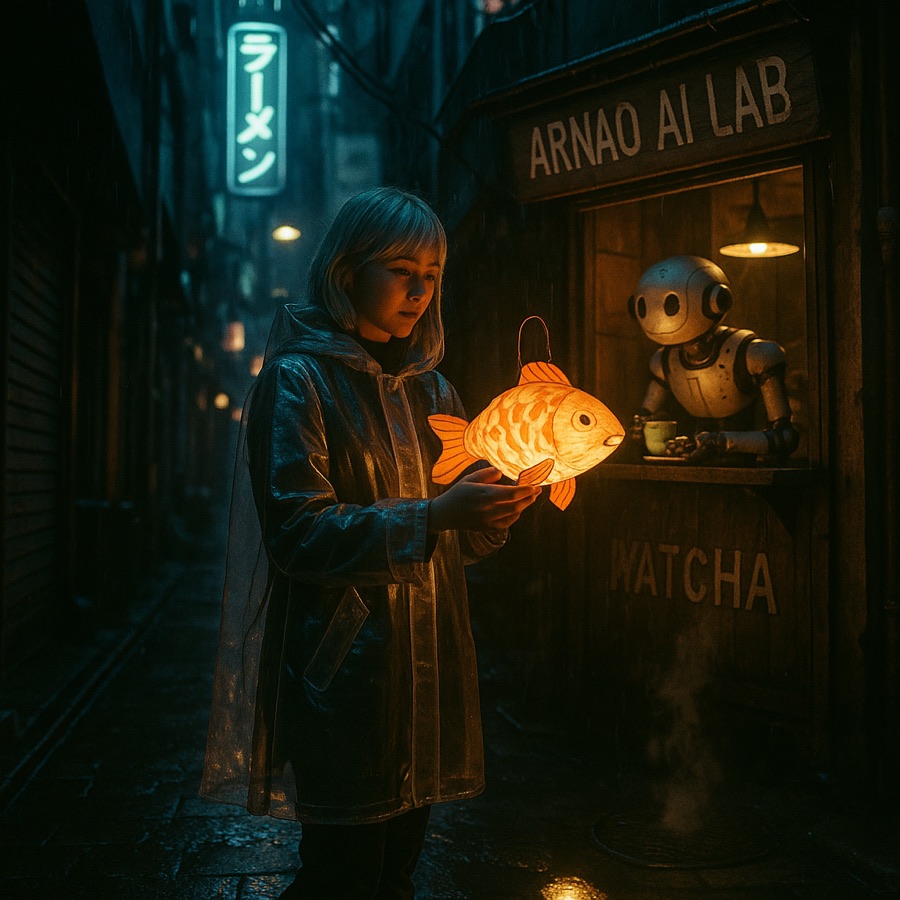
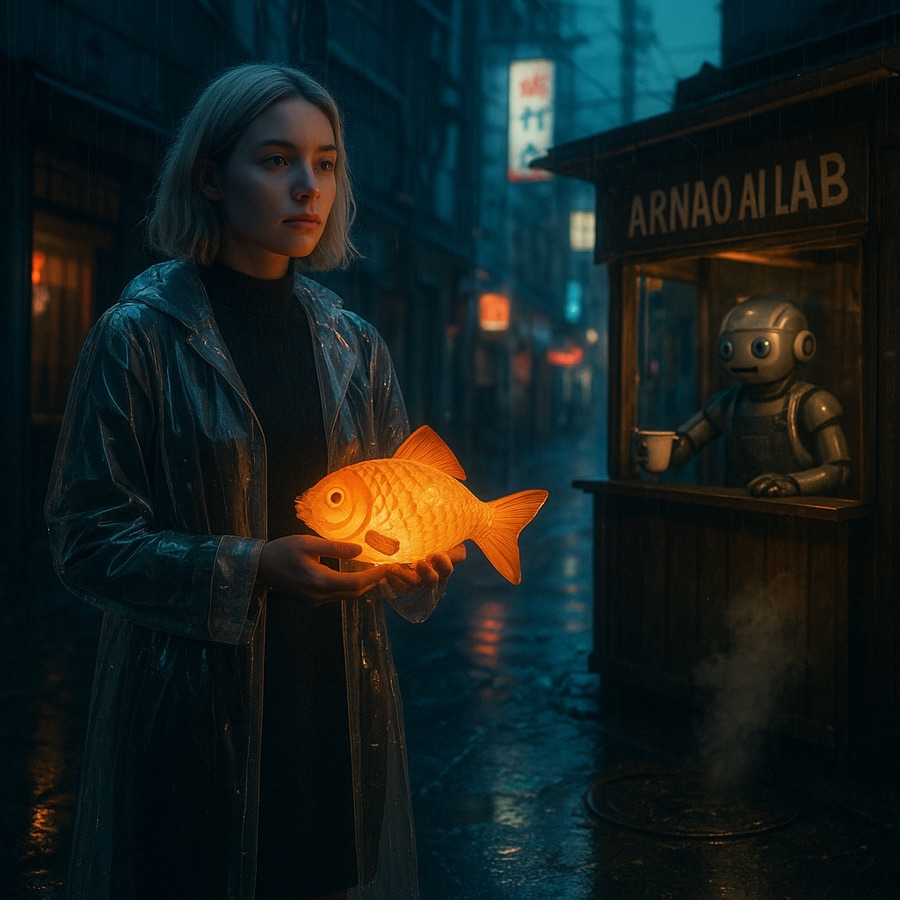
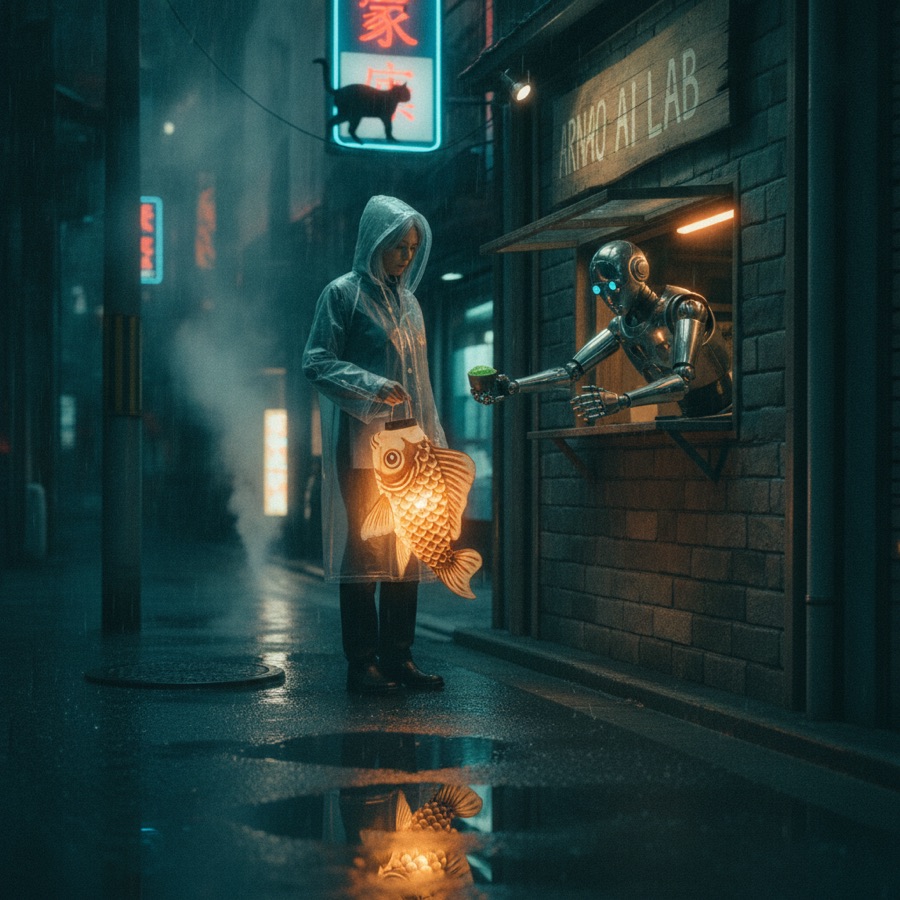
| Model | Provider | Sign Text | 3 Puddles | Cat on Wire | Aesthetic | Adherence | Latency | Cost |
|---|---|---|---|---|---|---|---|---|
| grok-imagine-image-quality 🏆 | xAI | ✓ | ✓ | ✓ | 9 | 9 | 6.2s | $0.050 |
| gpt-5.4-image-2 | OpenAI (OR) | ✓ | ✓ | ✓ | 9 | 9 | 180.2s | $0.228 |
| gemini-3-pro-image-preview | ✓ | ✗ | ✓ | 9 | 9 | 19.5s | $0.134 | |
| gemini-3.1-flash-image | Google (OR) | ✓ | ✗ | ✓ | 9 | 8 | 7.7s | $0.069 |
| grok-imagine-image | xAI | ✓ | ✗ | ✓ | 8 | 8 | 8.0s | $0.020 |
| gemini-3.1-flash-lite-image | Google (OR) | ✓ | ✗ | ✓ | 8 | 7 | 2.6s | $0.034 |
| gpt-image-1 | OpenAI | ✓ | ✗ | ✗ | 8 | 7 | 42.0s | $0.167 |
| gpt-5-image-mini | OpenAI (OR) | ✓ | ✗ | ✗ | 8 | 6 | 46.4s | $0.044 |
| gemini-2.5-flash-image | ✗ | ✗ | ✗ | 8 | 7 | 6.3s | $0.039 | |
| dall-e-3 | OpenAI | FAIL — model retired by OpenAI (“does not exist”) | ||||||
| grok-2-image | xAI | FAIL — retired, replaced by grok-imagine-image* | ||||||
| moonshot / deepseek | — | No image-generation API offered | ||||||
| local (ollama / host) | — | None local — ollama is text-only, no ComfyUI/mflux installed | ||||||
- HeadlinexAI’s grok-imagine-image-quality matched gpt-5.4-image-2’s perfect checklist at 1/30th the latency and 1/4.5th the cost. Gia’s image stack now routes winner → Nano Banana Pro → Nano Banana 2.
- NotableEvery 2026-era model except gemini-2.5-flash-image rendered “ARNAO AI LAB” exactly — text rendering is largely solved. Counting (“exactly three puddles”) remains the hardest test: only 2 of 9 passed.
- Catalog gapOpenRouter carries no Chinese image-output models today (no Qwen-Image, CogView, Seedream, or Hunyuan-Image) — only Google nano-banana and OpenAI GPT-5-image families.
- Harnessscripts/benchmarks/image-bench.py — idempotent, per-model reruns via --model, fail-soft error capture. Raw PNGs + results.json in workspace/benchmarks/images/2026-07-11/.
Realtime Voice / Speech-to-Speech Landscape — Jul 26, 2026
| Model | Provider | Multimodal | Tool calls | Barge-in | Price (audio) | Released | Harness note |
|---|---|---|---|---|---|---|---|
| gpt-realtime-2.1-mini 🏆 | OpenAI | audio+text | ✓ +reasoning | ✓ | ~$10/$20 /1M (~$0.04/min) | Jul 7 2026 | Gallery default. WebRTC, ephemeral token via /client_secrets. July drop closed the tool-calling gap. |
| gpt-realtime-2 | OpenAI | audio+text | ✓ GPT-5-class | ✓ | $32/$64 /1M | May 7 2026 | Flagship. HIGH-tier candidate; overkill for card nav. |
| Gemini 3.1 Flash Live | audio+video+img | ✓ (sync only) | ✓ | Flash-tier | Mar 24 2026 | Only native model that SEES. The gesture/camera fork — but frames leave device (RAI trade-off). | |
| Nova 2 Sonic | Amazon | audio | ✓ async | ✓ | $3/$12 /1M (~$0.015/min) | Dec 2025 | ~80% cheaper, AWS-native (Bedrock). Documented deployment target, not a running account. |
| grok-voice-think-fast-1.0 | xAI | audio | ✓ | ✓ | $0.05/min | Jun 29 2026 | OpenAI-Realtime compatible — swap base URL to wss://api.x.ai/v1/realtime. Zero-migration A/B. |
| ElevenAgents / CAI 2.0 | ElevenLabs | see+hear+files | ✓ +RAG | ✓ | platform | Jan 2026 | Best voice quality, sub-100ms. Composed platform — reserve for the cloned produced-voice layer. |
- HeadlineThe model is not the bottleneck: gpt-realtime-2.1-mini over WebRTC is native-live-mode-class tech. "Doesn't interact" is tools + turn-config + reliability, not the model — fixed in the gallery voice pass (v75).
- Gesture fork, resolvedHIGH tier stays OpenAI flagship; gesture stays local MediaPipe (~60fps, zero camera frames leave device). Streaming a webcam to a cloud model to detect a swipe is the less responsible design. Gemini native-vision is shelved as a labeled "frames leave device" experiment, not a tier.
- AWSNova 2 Sonic is the cheapest + AWS-native path, kept as a documented deployment target in the Mentor/Kiro PRD — the brand story doesn't require running it.
- SourcesOpenAI voice models · Gemini 3.1 Flash Live · Nova 2 Sonic · Grok Voice. Verified 2026-07-26.
Internal Fleet Benchmark — Jun 21, 2026
| Model | Avg Time | Cost / 4 Tasks | Pass Rate | Notes |
|---|
Research & Deep Dives
- Sakana FuguAn orchestration model that routes tasks to a team of specialist models. The “satanic fugu” concept in practice.
- AgentOSA unified command center for managing multiple agents with persistent memory and a shared interface across AI models. A project at agentos.arnao.ai is feasible.
- Model MonitoringA lightweight cron polls RSS from Hugging Face, arXiv, and top AI labs every 4 hours to surface new releases automatically.